
Written by: The Editorial Team
Published: 14 Oct 2026
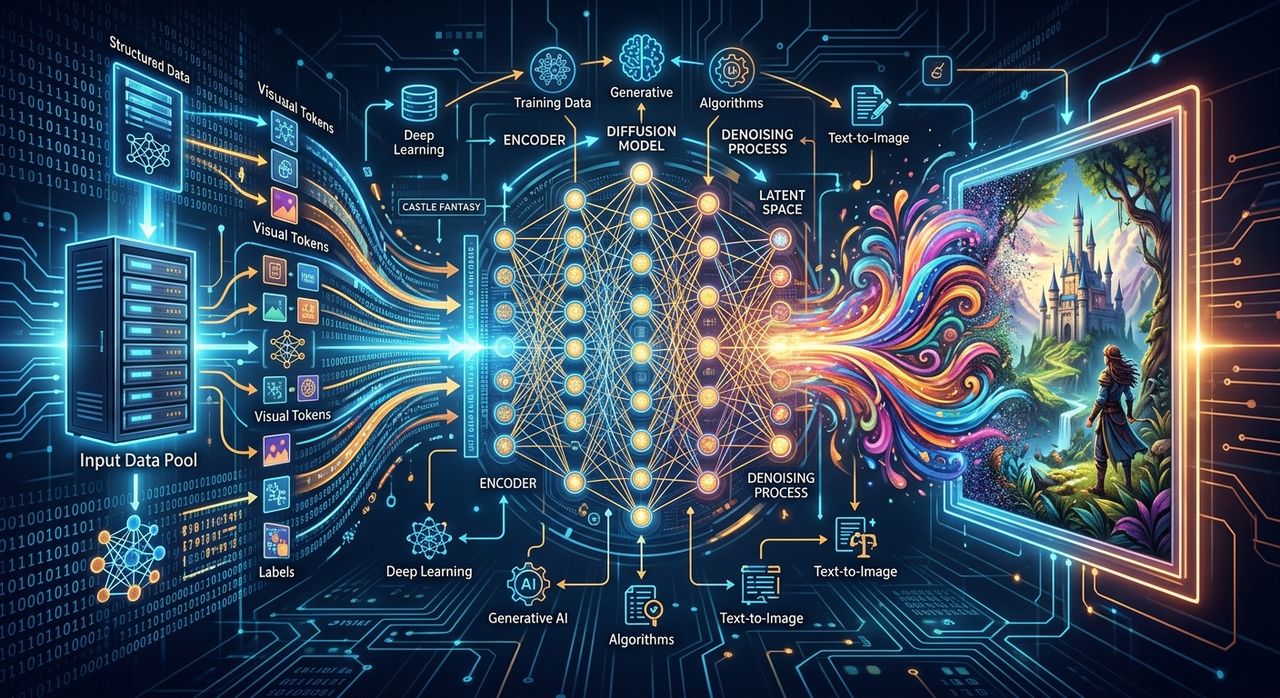
Typing a sentence and watching a fully rendered image appear feels like magic. But there is actual science behind every pixel. AI image generators are built on years of machine learning research, mathematical models, and datasets so large they are difficult to fully comprehend. Understanding how they work makes you a better user and gives you a genuine appreciation for what these tools can do. Here are 25 facts that pull back the curtain on the entire process, from the very first line of training data to the moment a finished image lands on your screen.
Key Takeaway: AI image generators convert text into images through a chain of connected processes, starting with training on billions of labeled image-text pairs and ending with a denoising loop that sculpts visual detail from pure noise. The words you type are broken into tokens, which guide the model at every step of that loop. The better your input, the more coherent the output. These systems are not magic, but they are genuinely impressive engineering built on decades of research.
How AI Image Generators Learn From Data
Fact 1: They are trained on billions of image-text pairs.
Every AI image generator begins with a training phase. Models are exposed to hundreds of millions, sometimes billions, of images paired with captions or alt-text scraped from the internet. The model learns which visual patterns correspond to which words by seeing the same concepts described and depicted in countless different ways across different styles, cultures, and media types.
Fact 2: The training data shapes the model's visual worldview.
Whatever is overrepresented in training data shows up more confidently in outputs. If the dataset skews toward a particular cultural aesthetic or photographic style, the model defaults to that. This is why different generators feel stylistically distinct even when given identical prompts. The data is the foundation everything else is built on.
Fact 3: Labels and captions carry enormous weight.
Raw images alone are not enough. Each image needs a text description so the model learns what it is looking at. Researchers use a combination of human-written captions, auto-generated descriptions, and metadata to build these paired datasets. Poor labeling at this stage can produce models that confidently generate the wrong thing.
Fact 4: Early systems used competing neural networks.
Before latent diffusion dominated the field, the best image generators relied on Generative Adversarial Networks, a framework where two neural networks compete. One generates images, the other tries to detect fakes. This competition pushed output quality higher over time and was the dominant architecture for several years before newer approaches overtook it.
Fact 5: Training costs run into the millions of dollars.
The compute required to train a frontier image model is staggering. Some models have been trained on thousands of GPUs running for weeks. This is why only a handful of well-funded organizations have built these models from scratch. Everyone else builds on top of publicly released weights or APIs.
How Text Becomes Visual Information
Fact 6: Your text prompt becomes numbers before anything visual happens.
Before the model does anything with your words, it converts them into a numerical representation called an embedding. This vector captures the semantic meaning of your prompt in a form the neural network can process mathematically. The visual generation process never directly reads your text; it reads these numbers.
Fact 7: Tokens are the unit of meaning.
Text is broken into tokens, which are chunks of characters. A token might be a full word, part of a word, or punctuation. Each token gets mapped to a vector, and the model interprets the relationships between these vectors to understand what you are describing. A word like "photorealistic" may be a single token, while "impressionistic" might be split across two.
Fact 8: Transformers handle the language side of the model.
The language component of most modern image generators uses a transformer architecture. Originally developed for text tasks, transformers excel at capturing long-range relationships between words. This matters when your prompt contains multiple descriptive clauses that need to interact, such as a subject, a style, and a lighting condition all specified together.
Fact 9: The model reasons about images in a compressed space.
Rather than operating directly on full-resolution pixel grids, most modern generators work in a compressed representation called latent space. This is vastly more computationally efficient and lets the model reason about image content at a higher level of abstraction. Think of it as working with a rough sketch rather than a finished painting.
Fact 10: A decoder converts abstract representations back into pixels.
Once the model finishes working in latent space, a component called the decoder converts that compressed representation back into actual pixel values. The decoder is trained to reconstruct high-quality images from latent codes. This final step is where the visible image is produced.
Latent Diffusion and the Noise Removal Loop
Fact 11: Diffusion models work by gradually removing noise.
The core mechanism in today's best generators is diffusion. The model starts with an image that is pure random noise, then removes noise in steps, guided at each step by your text prompt. Each iteration makes the image slightly more coherent, more structured, and more aligned with what you asked for.
Fact 12: Denoising runs across dozens of steps.
A typical diffusion run involves anywhere from 20 to 100 denoising steps. More steps generally produce sharper, more detailed images but take longer to compute. Many generators let you adjust the step count, giving you a trade-off between speed and quality depending on your needs.
Fact 13: Stable Diffusion made the technology widely accessible.
The release of Stable Diffusion in 2022 was a pivotal moment. It was the first high-quality latent diffusion model released publicly with open weights, allowing researchers, developers, and hobbyists to build on top of it freely. Much of the tooling and community knowledge around image generation today traces back to that release.
Fact 14: Guidance scale controls how closely the model follows your instructions.
Most generators expose a setting called classifier-free guidance. A higher value means the model adheres more literally to your prompt. A lower value gives the model more creative latitude. The optimal setting varies by model and use case, but most users get the best results somewhere in the middle range.
Fact 15: The same prompt produces a different image every time.
Diffusion starts from random noise, so two runs with identical prompts produce different results. Generators let you lock in a specific seed number to fix the starting noise pattern, making results reproducible. This is useful when you want to iterate on a composition without completely regenerating everything.
Token Interpretation and Getting Better Outputs
Fact 16: Word order within your prompt influences the output.
The transformer pays attention to where in the prompt each token appears. Words that appear earlier often carry more weight in shaping the output. Placing your most important descriptors near the beginning of a prompt tends to produce stronger adherence to those elements, especially on complex or long prompts.
Fact 17: Adjectives and nouns are processed as clusters, not in isolation.
When you write "warm golden afternoon light," the model does not interpret each word independently. It processes them as a cluster of meaning that maps to a cohesive visual concept. This is why specific descriptive phrases often outperform vague single words, even when the single word technically covers the same ground.
Fact 18: Negative prompts tell the model what to avoid.
Most modern generators accept a negative prompt field alongside the main one. Words in the negative prompt get pushed away from during the denoising process. Listing descriptors like "blurry," "distorted anatomy," or "watermark" in the negative prompt can meaningfully improve output quality, especially for photorealistic styles.
Fact 19: Specific word choices steer the model's stylistic interpretation.
Writing "oil painting" versus "photograph" versus "3D render" sends the model down entirely different visual paths. Referencing a recognized artistic style or medium in your prompt acts as a shortcut to a whole aesthetic cluster the model absorbed during training. Understanding these shortcuts is the core skill in text-to-image work, and a well-organized prompting guide breaks down exactly how these word choices interact so you can steer outputs with far more precision.
Fact 20: Context window limits are real.
Like all transformer-based systems, image generators have a maximum token count for prompts. Exceeding that limit causes the later parts of your prompt to be ignored silently. Keeping prompts focused and under the limit is practical advice, not just preference. A long prompt that overflows the context may actually perform worse than a shorter, tighter one.
Real-World Uses and What People Build
Fact 21: Concept art is one of the biggest professional applications.
Game studios, film productions, and advertising agencies use these tools to produce concept art and mood boards in hours rather than weeks. The tools do not replace artists but fundamentally change what the earliest stages of a creative project look like and how many ideas a team can evaluate quickly.
Fact 22: You do not need design skills to get started.
You do not need to know illustration, photo editing, or color theory to produce visually coherent images with these tools. A plain-language description is enough. An online AI image generator that runs directly in a browser means there is no software to install and no technical setup required to try the technology for the first time.
Fact 23: Fine-tuning lets developers add custom styles and subjects.
Developers can take a base model and train it further on a small custom dataset. This is how people create models that reliably draw in a specific style, generate product images that match a brand's visual identity, or produce consistent character designs across a long project. Fine-tuned models dramatically reduce the prompting effort required to hit a specific look.
Fact 24: Inpainting and outpainting extend the tools beyond generation.
Inpainting lets you select a region of an existing image and regenerate just that portion, leaving everything else intact. Outpainting extends an image beyond its original borders by generating new content that matches the existing visual context. These capabilities make AI image tools useful for editing and retouching workflows, not just creation from a blank slate.
Fact 25: The models keep getting smaller and faster.
Early state-of-the-art models required powerful server hardware to run at any reasonable speed. Newer architectures have made it possible to run capable models on consumer GPUs and even mobile devices. The gap between what runs in a browser and what runs on a data center continues to close, and the pace of improvement has not slowed.
What First-Time Users Notice Right Away
Several behaviors catch people off guard when they first use these tools:
- Hands and fingers have historically been where models make the most errors, though newer versions have improved substantially
- Adding the word "realistic" to a prompt does not always make images more realistic; model-specific style keywords often work better
- Very long prompts do not consistently outperform short, precise ones, and can actually hurt results if they overflow the context window
- Changing just a single word in a prompt can produce a wildly different image, even with the same seed
- Resolution and aspect ratio settings have a larger impact on composition and subject placement than most users anticipate
How the Main Architectural Approaches Compare
| Approach | Core Mechanism | Strengths |
|---|---|---|
| Latent Diffusion | Denoises compressed representations guided by text embeddings | High-quality photorealistic and artistic outputs |
| GAN | Generator vs. discriminator competition during training | Fast generation, strong early results on faces |
| Autoregressive | Predicts image tokens sequentially, like a language model | Reliable text rendering inside images |
| Flow Matching | Learns direct paths from noise to data distributions | Faster sampling with fewer denoising steps |
What These 25 Facts Add Up To
These facts are not isolated trivia. They form a chain. Training data shapes what the model knows. That knowledge gets encoded into weights. A prompt arrives as tokens, becomes embeddings, and those embeddings guide a denoising process running through latent space. A decoder turns that abstract process into something visible. Each fact connects to the next.
Understanding the chain gives you real leverage over your results. Word order, descriptor specificity, negative prompts, guidance scale, seed numbers, and step count are all controls you can use. Getting good at using them is a learnable skill. The entry point is accessible to anyone with a browser and a curious mind, but the ceiling for what an informed user can produce is genuinely high.
Was this page helpful?
Our commitment to delivering trustworthy and engaging content is at the heart of what we do. Each fact on our site is contributed by real users like you, bringing a wealth of diverse insights and information. To ensure the highest standards of accuracy and reliability, our dedicated editors meticulously review each submission. This process guarantees that the facts we share are not only fascinating but also credible. Trust in our commitment to quality and authenticity as you explore and learn with us.